Windows: move boundaries, avoid rescanning
“Our analyzer receives abba. How long is its longest contiguous span with no repeated character?”
The answer is 2, not 3. Trace what the second b invalidates and why seeing the final a must not move the left boundary backward.
The coding-practice chapter will apply this tool to complete problems. Here, focus on the mechanism and trace how its state changes.
Working example: Find the longest substring without repeated characters. abba → 2.
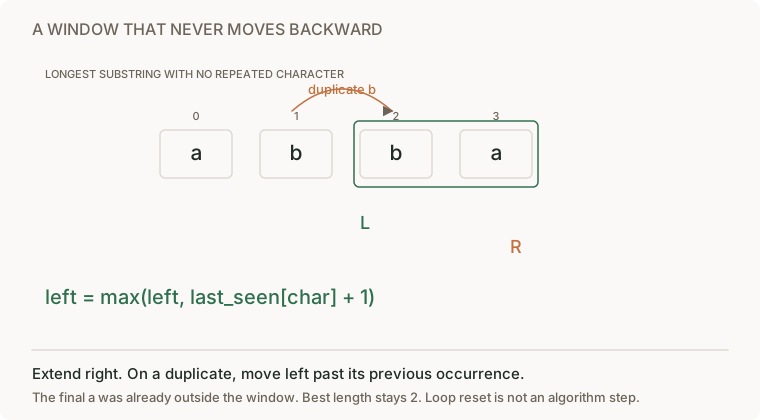
The idea: The active window contains unique characters. Move left to max(left, last_seen[char] + 1).
First, what is a window?
A substring is a contiguous piece of text. In "abba", "ab" and "bb" are substrings; "aa" is not. A window is the current substring between inclusive positions left and right. Its length is right - left + 1. We want the longest window whose characters are all different.
text = "abba"
left, right = 0, 1
print(text[left:right + 1])  # "ab"; Python's slice end is exclusive
last_seen = {"a": 0, "b": 1}  # character -> latest position
On the next b at position 2, the b at position 1 invalidates "abb". Shift left to 2. On the final a, its old position 0 lies outside the current window, so left must stay at 2. The max in the formula prevents the boundary from moving backward.
Character at right |
left after update |
Current window | Best length |
|---|---|---|---|
a at 0 |
0 | "a" |
1 |
b at 1 |
0 | "ab" |
2 |
b at 2 |
2 | "b" |
2 |
a at 3 |
2 | "ba" |
2 |
Read the animation: each shift discards a prefix, never a suffix. The dictionary remembers the last position of each character, unlike the two-sum dictionary, which remembers the first position of each number.
left = max(left, last_seen.get(char, -1) + 1)
best = max(best, right - left + 1)
last_seen[char] = right
get(char, -1) returns −1 when the key has not appeared. That makes a first occurrence keep left at 0. Write these three lines in this order: move the boundary, measure the valid window, then record the current position.
Check the mechanism
Predict each expected result, then trace the state that produces it. Explain the boundary case before opening the reference.
Cost: Repeatedly check substrings: up to O(n³). Last-seen window: O(n) time, O(u) space for u distinct characters.
01 · Try this input
- Input / starting state
"abba"- Expected result
- 2
Why: "ab" and "ba" qualify; "abb" does not.
02 · Try this input
- Input / starting state
"aaaa"- Expected result
- 1
Why: Every longer window repeats a.
03 · Try this input
- Input / starting state
""- Expected result
- 0
Why: No characters, so no nonempty window.
04 · Try this input
- Input / starting state
"dvdf"- Expected result
- 3
Why: "vdf" is unique; the old d must be discarded.
05 · Try this input
- Input / starting state
"tmmzuxt"- Expected result
- 5
Why: "mzuxt"; the final t does not move left backward.
Here n is the number of characters and u is the number of distinct characters stored. Each character enters the window once and left only moves right, so total scan work is O(n); the dictionary can hold up to u keys. The naïve version can check O(n²) substrings and spend up to O(n) examining each.
Pass before moving on: Trace all four characters of abba without moving left backward.
Return the substring, not only its length. Define which answer wins a tie.
After attempting: reference and explanation
Compare longest_unique in algorithms.py (download file, source below). Use pattern notes for the invariant and contracts for complexity edge cases. Reimplement tomorrow without copying.
"""Reference solutions. Try the exercises in README.md before opening this file."""
from collections import Counter, OrderedDict, deque
from heapq import heappop, heappush, nlargest


def two_sum(nums, target):
    visited = {}
    for j, value in enumerate(nums):
        complement = target - value
        if complement in visited:
            return visited[complement], j
        visited.setdefault(value, j)
    return None


def longest_unique(text):
    left = best = 0
    last_seen = {}
    for right, char in enumerate(text):
        left = max(left, last_seen.get(char, -1) + 1)
        best = max(best, right - left + 1)
        last_seen[char] = right
    return best


def subarray_sum(nums, target):
    prefix_counts = {0: 1}
    prefix = result = 0
    for value in nums:
        prefix += value
        result += prefix_counts.get(prefix - target, 0)
        prefix_counts[prefix] = prefix_counts.get(prefix, 0) + 1
    return result


def lower_bound(nums, target):
    lo, hi = 0, len(nums)
    while lo < hi:
        mid = lo + (hi - lo) // 2
        if nums[mid] < target:
            lo = mid + 1
        else:
            hi = mid
    return lo


def merge_intervals(intervals):
    """Closed intervals; touching endpoints merge. Does not mutate input."""
    out = []
    for start, end in sorted(intervals):
        if start > end:
            raise ValueError('reversed interval')
        if out and start <= out[-1][1]:
            out[-1][1] = max(out[-1][1], end)
        else:
            out.append([start, end])
    return out


def top_k_frequent(nums, k):
    if k < 0:
        raise ValueError('k must be nonnegative')
    counts = Counter(nums)
    # Higher count wins; smaller value breaks ties deterministically.
    return nlargest(k, counts, key=lambda value: (counts[value], -value))


def islands(grid):
    """Rectangular list of lists of '0'/'1'; input remains unchanged."""
    if not grid:
        return 0
    cols = len(grid[0])
    if any(len(row) != cols or any(x not in ('0', '1') for x in row) for row in grid):
        raise ValueError('expected rectangular binary grid')
    seen = set()
    count = 0
    for r, row in enumerate(grid):
        for c, value in enumerate(row):
            if value != '1' or (r, c) in seen:
                continue
            count += 1
            seen.add((r, c))
            queue = deque([(r, c)])
            while queue:
                x, y = queue.popleft()
                for a, b in ((x-1, y), (x+1, y), (x, y-1), (x, y+1)):
                    if 0 <= a < len(grid) and 0 <= b < cols and grid[a][b] == '1' and (a, b) not in seen:
                        seen.add((a, b))  # Mark on enqueue, not dequeue.
                        queue.append((a, b))
    return count


def course_order(n, prerequisites):
    """Each pair is (course, prerequisite); [] means a cycle or no courses."""
    if n < 0:
        raise ValueError('negative course count')
    adjacency = [set() for _ in range(n)]
    degree = [0] * n
    for course, prerequisite in prerequisites:
        if not 0 <= course < n or not 0 <= prerequisite < n:
            raise ValueError('course outside graph')
        if course not in adjacency[prerequisite]:
            adjacency[prerequisite].add(course)
            degree[course] += 1
    queue = deque(i for i, d in enumerate(degree) if d == 0)
    order = []
    while queue:
        node = queue.popleft()
        order.append(node)
        for neighbor in adjacency[node]:
            degree[neighbor] -= 1
            if degree[neighbor] == 0:
                queue.append(neighbor)
    return order if len(order) == n else []


def shortest_paths(n, edges, source):
    """Directed nonnegative weighted graph; unreachable distances are infinity."""
    if not 0 <= source < n:
        raise ValueError('invalid source')
    graph = [[] for _ in range(n)]
    for u, v, weight in edges:
        if not 0 <= u < n or not 0 <= v < n or weight < 0:
            raise ValueError('invalid edge')
        graph[u].append((v, weight))
    distance = [float('inf')] * n
    distance[source] = 0
    heap = [(0, source)]
    while heap:
        cost, node = heappop(heap)
        if cost != distance[node]:
            continue
        for neighbor, weight in graph[node]:
            candidate = cost + weight
            if candidate < distance[neighbor]:
                distance[neighbor] = candidate
                heappush(heap, (candidate, neighbor))
    return distance


class LRU:
    """Capacity in entries; None denotes a miss. Not thread-safe."""
    def __init__(self, capacity):
        if capacity < 0:
            raise ValueError('negative capacity')
        self.capacity = capacity
        self.data = OrderedDict()

    def get(self, key):
        if key not in self.data:
            return None
        self.data.move_to_end(key)
        return self.data[key]

    def put(self, key, value):
        if self.capacity == 0:
            return
        self.data[key] = value
        self.data.move_to_end(key)
        if len(self.data) > self.capacity:
            self.data.popitem(last=False)


def min_coins(coins, amount):
    if amount < 0 or any(c <= 0 for c in coins):
        raise ValueError('nonnegative amount and positive coins required')
    dp = [0] + [amount + 1] * amount
    for total in range(1, amount + 1):
        for coin in coins:
            if coin <= total:
                dp[total] = min(dp[total], dp[total-coin] + 1)
    return -1 if dp[amount] > amount else dp[amount]


def daily_temperatures(temperatures):
    answer = [0] * len(temperatures)
    stack = []
    for i, temp in enumerate(temperatures):
        while stack and temperatures[stack[-1]] < temp:
            previous = stack.pop()
            answer[previous] = i - previous
        stack.append(i)
    return answer


def word_exists(board, word):
    """4-neighbor word search; do not reuse a cell or mutate the board."""
    if not word:
        return True
    if not board:
        return False
    cols = len(board[0])
    if any(len(row) != cols for row in board):
        raise ValueError('ragged board')
    def visit(r, c, index, used):
        if not (0 <= r < len(board) and 0 <= c < cols) or (r, c) in used or board[r][c] != word[index]:
            return False
        if index == len(word) - 1:
            return True
        used.add((r, c))
        found = any(visit(a, b, index+1, used) for a, b in ((r+1,c),(r-1,c),(r,c+1),(r,c-1)))
        used.remove((r, c))
        return found
    return any(visit(r, c, 0, set()) for r in range(len(board)) for c in range(cols))


class Trie:
    END = object()

    def __init__(self):
        self.root = {}

    def insert(self, word):
        node = self.root
        for char in word:
            node = node.setdefault(char, {})
        node[self.END] = True

    def contains(self, word):
        node = self.root
        for char in word:
            if char not in node:
                return False
            node = node[char]
        return self.END in node